Tag: Llama.cpp
-
Vulkan GPU Passthrough Secret for Llama CPP
Learn how to use Podman to pass Vulkan GPU acceleration to llama.cpp for high performance local AI inference on Fedora.
Written by
-
Give Your Local LLM Superpowers With Zero Dependencies Using PHP MCP Bridge
Transform your isolated llama.cpp server into a fully capable AI agent with a single PHP file.
Written by
-
Enterprise GPUs Like AMD Mi60 Vs Consumer GPUs Plus Used Nvidia Enterprise Cards For LLMs Stable Diffusion And Gaming
Discover how enterprise GPUs like the AMD MI60 and used Nvidia cards outperform consumer GPUs for LLMs Stable Diffusion and gaming with massive VRAM advantages and precision format support
Written by
-
Stop Paying For Copilot: The NetBeans 29 Local AI Secret
Unlock professional AI code assistance directly in NetBeans 29 using llama.cpp and PHP.
Written by
-
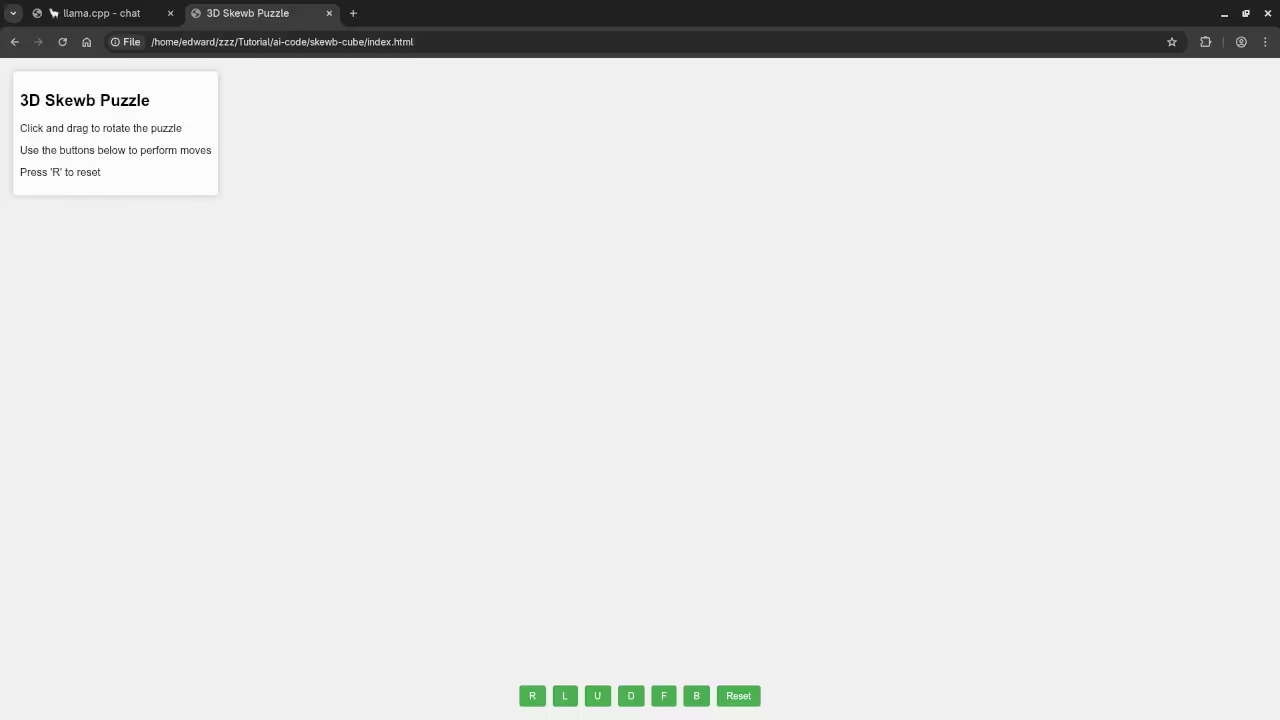
AI Generated Skewb Puzzle Solutions Using Qwen3 On Fedora
Introduction The Skewb is a unique corner turning twisty puzzle.
Written by
-
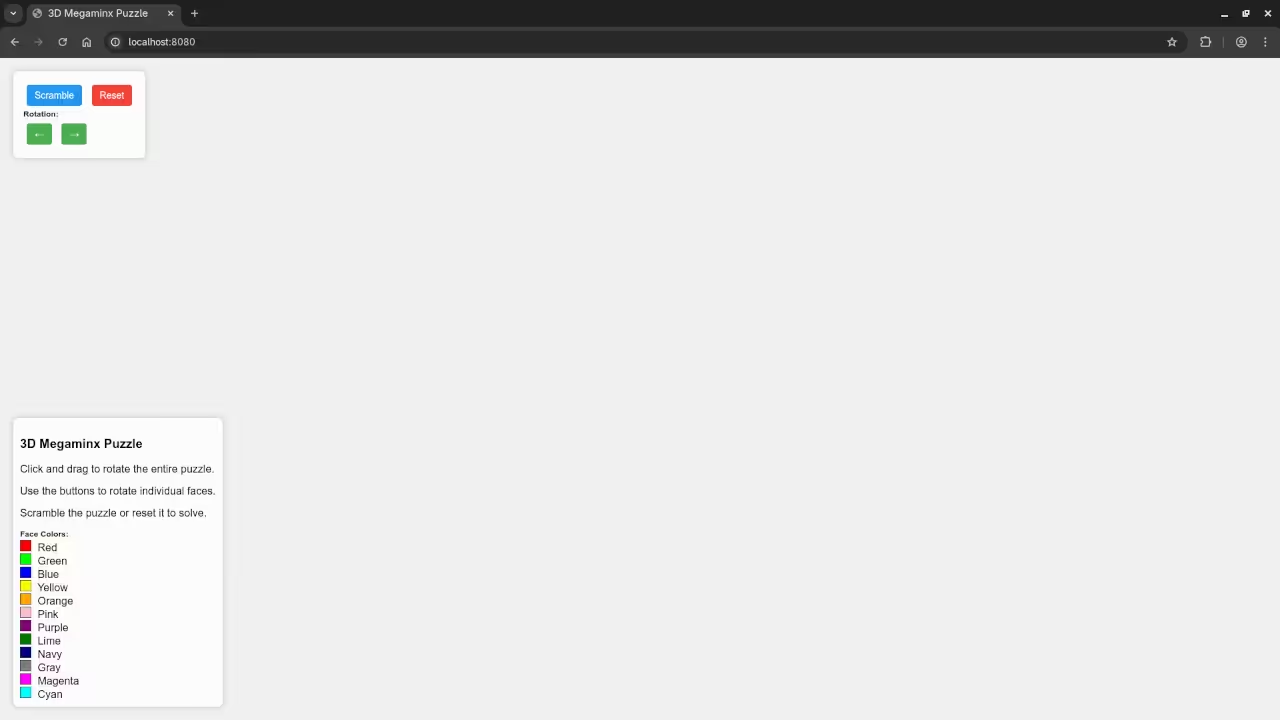
Generating a Megaminx with Qwen3 and HTML5
Introduction to Megaminx Generation Creating a Megaminx with HTML5 code is fun.
Written by
-
Understanding Local AI Architecture GGUF And Quantization
Introduction Local AI development is becoming very popular for Linux users.
Written by