The Secret Of Legacy VRAM
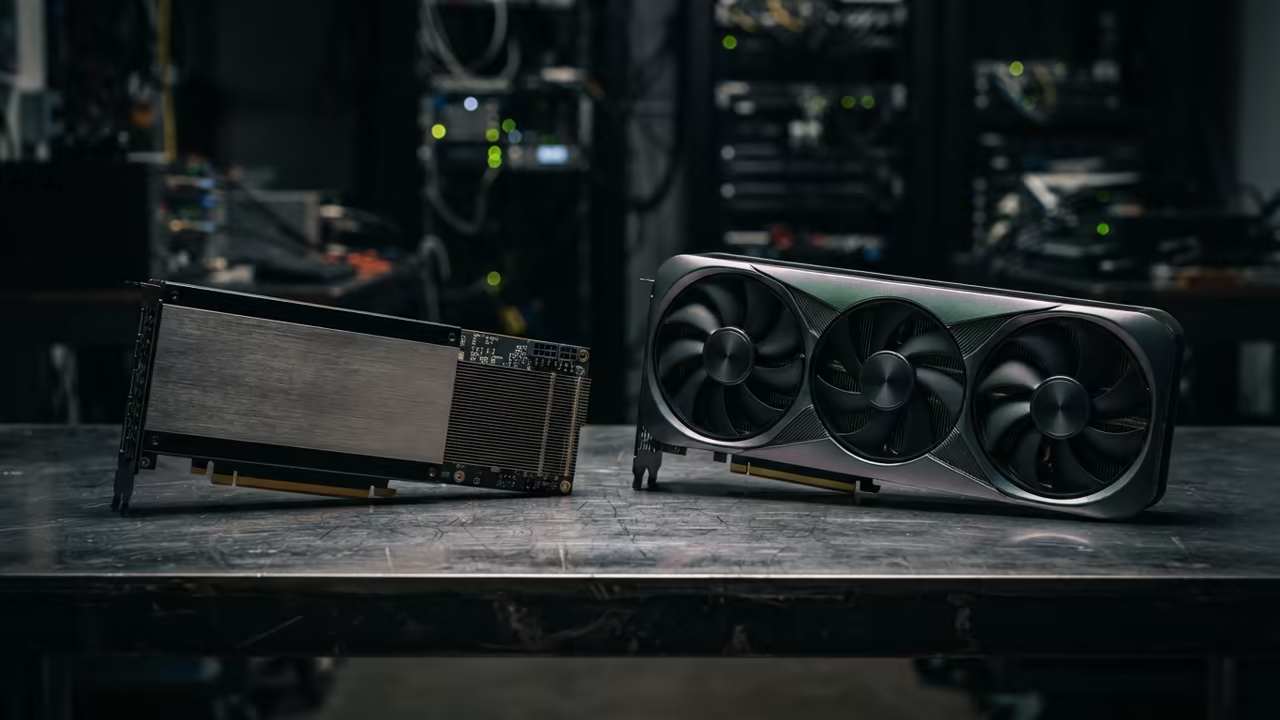
Most people throw thousands of dollars at the newest RTX 5090 for AI. They ignore the dusty server racks full of ten year old silicon.
These legacy enterprise cards offer a secret path to massive VRAM. You can acquire professional memory for a fraction of the cost.
Disclaimer: I may earn a commission from purchases made through these links at no extra cost to you.


The shock comes when a hundred dollar Tesla P100 out capacity a mid range card. It is a brutal realization for the average consumer enthusiast.
The Experience Of Server Hardware
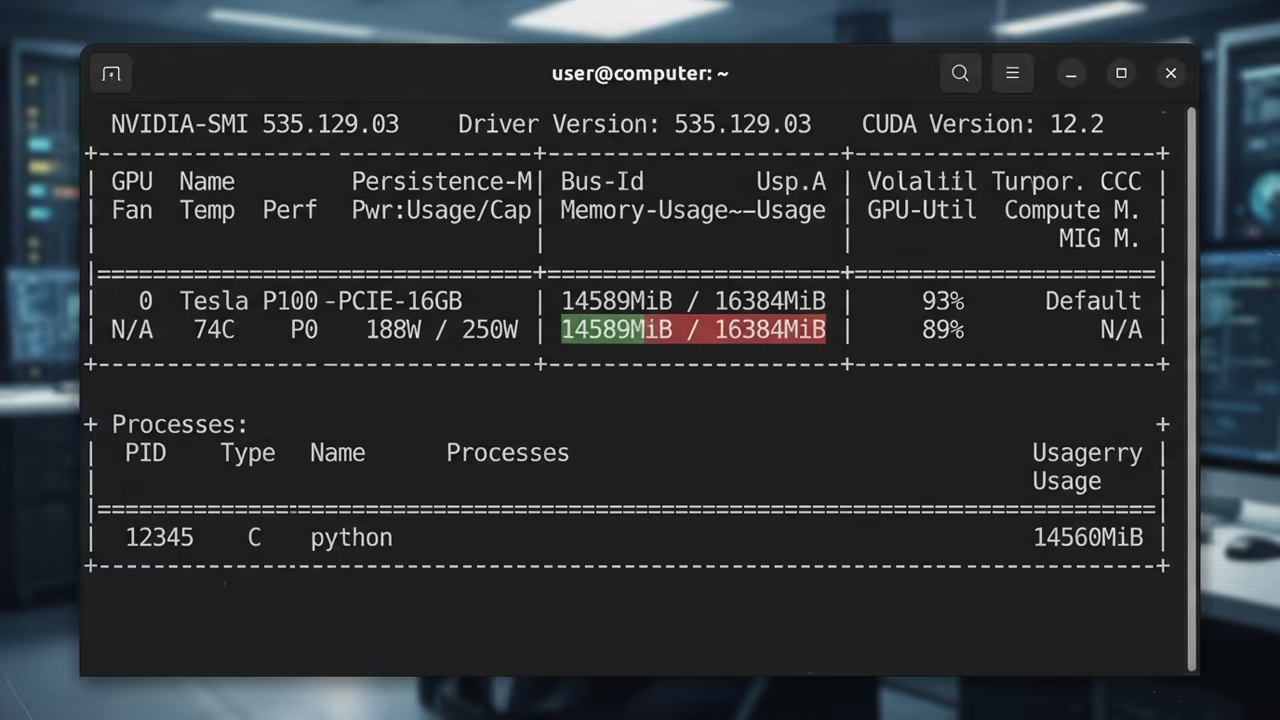
Implementing these old beasts feels like discovering a hidden cheat code. There is a specific thrill in seeing a 7B parameter model load perfectly.
The system hums as the HBM2 memory handles the token stream. You feel the power of server grade hardware in a home office.
The Technical Divide Of 2026
The technical divide between 2016 and 2026 is an absolute canyon. New RTX 5090 cards use GDDR7 memory for insane bandwidth speeds.
The 5090 hits nearly 1800 gigabytes per second of memory throughput. Meanwhile the Tesla P100 relies on older HBM2 technology from the Pascal era.
VRAM Per Dollar Economics
The real magic is the VRAM per dollar ratio. A used P100 costs roughly six dollars per gigabyte of memory.
A new consumer card often costs nearly thirty dollars per gigabyte. This gap allows budget builders to run larger models locally.
| Parameter | Description | Value |
|---|---|---|
| Tesla P100 | Enterprise Pascal | 16 GB HBM2 |
| RTX 5090 | Consumer Blackwell | 32 GB GDDR7 |
| Arc B780 | Consumer Battlemage | 16 GB GDDR6 |
| Parameter | Description | Value |
However you must accept the lack of modern Tensor cores. These old cards cannot use the mixed precision acceleration of 2026.
Navigating The Driver Minefield
The driver landscape is a dangerous minefield for the unwary. Nvidia still provides legacy support for Compute Capability 6.0 devices.
AMD is a different story for the budget hunter. Modern ROCm stacks have completely abandoned 2016 era FirePro hardware.
Attempting to run current LLM pipelines on old AMD gear is futile. You will face broken dependencies and unmaintained driver kernels.
The Insider Cooling Secret
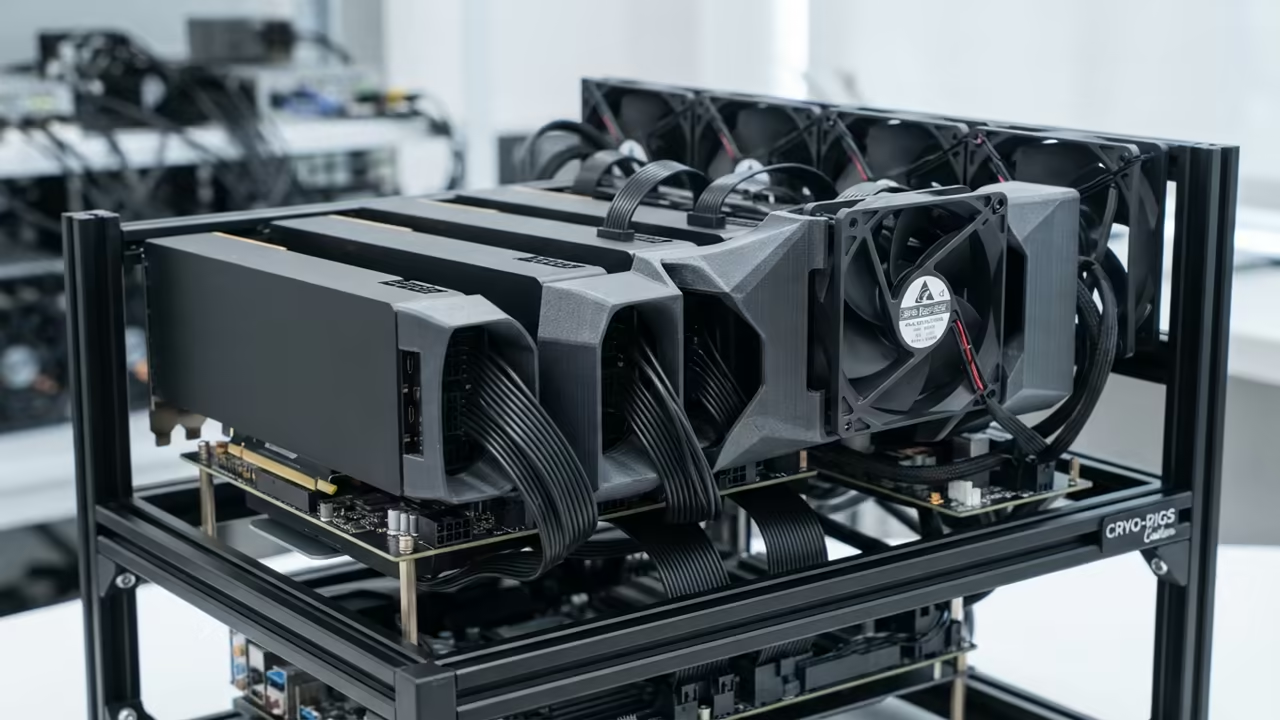
To make a Tesla P100 work you need a custom cooling solution. These cards are passive and will overheat in minutes without airflow.
Print a 3D shroud and attach a high static pressure fan. This insider detail prevents your hundred dollar investment from melting.
You should use the following configuration in llama.cpp for older CUDA devices. This ensures the model fits within the limited legacy compute boundaries.
# Use the following for quantized inference on Pascal
./main -m models/7B-quantized.gguf -ngl 32 --tensor_split 1,0
This setup connects directly to our previous deep dives on VRAM optimization. It builds upon the architectural breakthroughs found in our self hosting guides.
Performance Reality Check
The raw compute throughput of 2026 hardware is objectively superior. A 5080 will destroy a P100 in raw training speed.
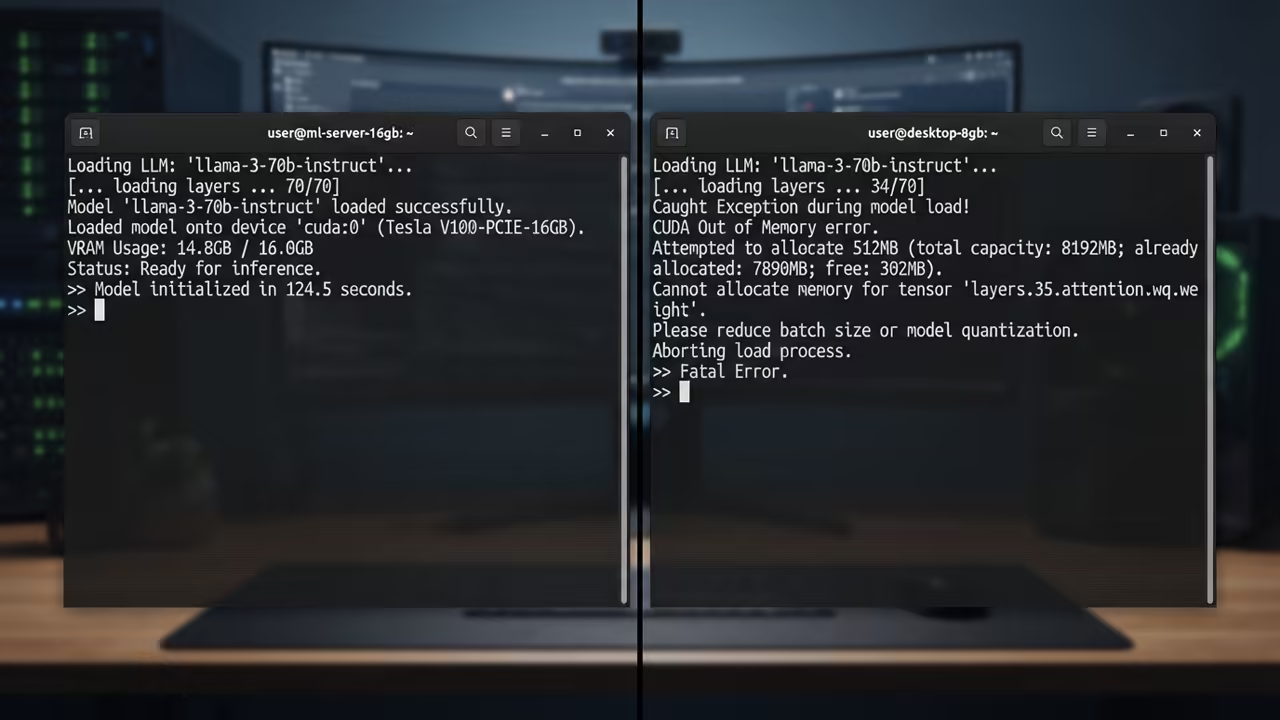
But for pure inference the VRAM capacity remains the ultimate king. You cannot run a model if it does not fit in memory.
Learning and Support
Reach out for personalized technical help to optimize your legacy GPU cluster. Dive deeper into the world of budget AI with our online tutorials.
Online Tutorials & Technical Help: https://ojambo.com/contact
🚀 Recommended Resources
Disclosure: Some of the links above are referral links. I may earn a commission if you make a purchase at no extra cost to you.
Leave a Reply