The Hidden Cost of Precision Shifting
Eliminate VRAM waste in inefficient pipelines that kill your generation speed. Discover why native BF16 execution on enterprise hardware leaves consumer setups in the dust.
You might believe that all BF16 support is created equal across different software stacks. This assumption is a dangerous trap for anyone building a local AI powerhouse.
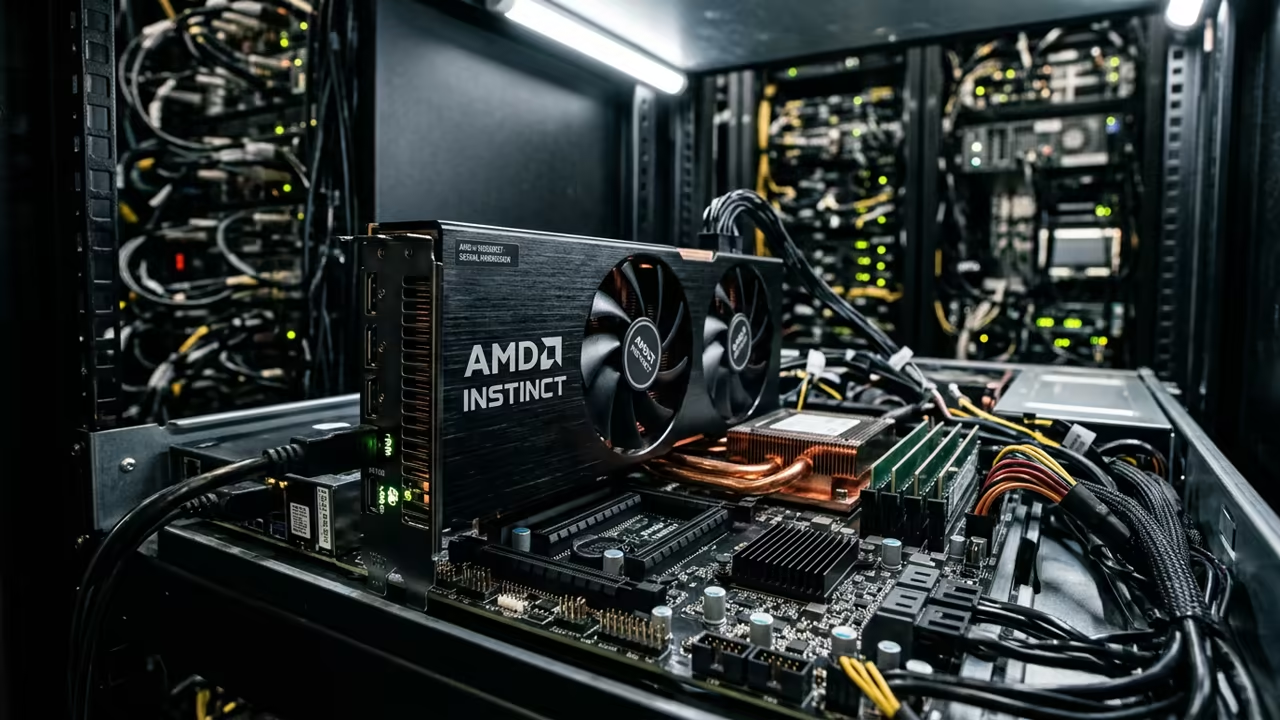
Many users see their AMD Instinct Mi60 struggle with the GGML implementation while Fibo 2 flies. This discrepancy creates a massive frustration for those investing in used enterprise gear.
Disclaimer: I may earn a commission from purchases made through these links at no extra cost to you.


The secret lies in the architectural difference between high level frameworks and lightweight C++ implementations. You are fighting a battle against the hidden casting tax in your pipeline.
The Experience of Native Execution
Implementing native BF16 on a Mi60 feels like removing a governor from a supercar. The generation speed stabilizes and the VRAM usage becomes predictable and efficient.
It is an exhilarating shift when the hardware finally breathes and processes tensors natively. You can finally leverage those 32GB of VRAM without the typical performance penalties.
For those scaling their local AI infrastructure this optimization is the ultimate game changer. Reach out to my consultation services for high tier technical project scales.
Architectural Breakdown of BF16 on Mi60
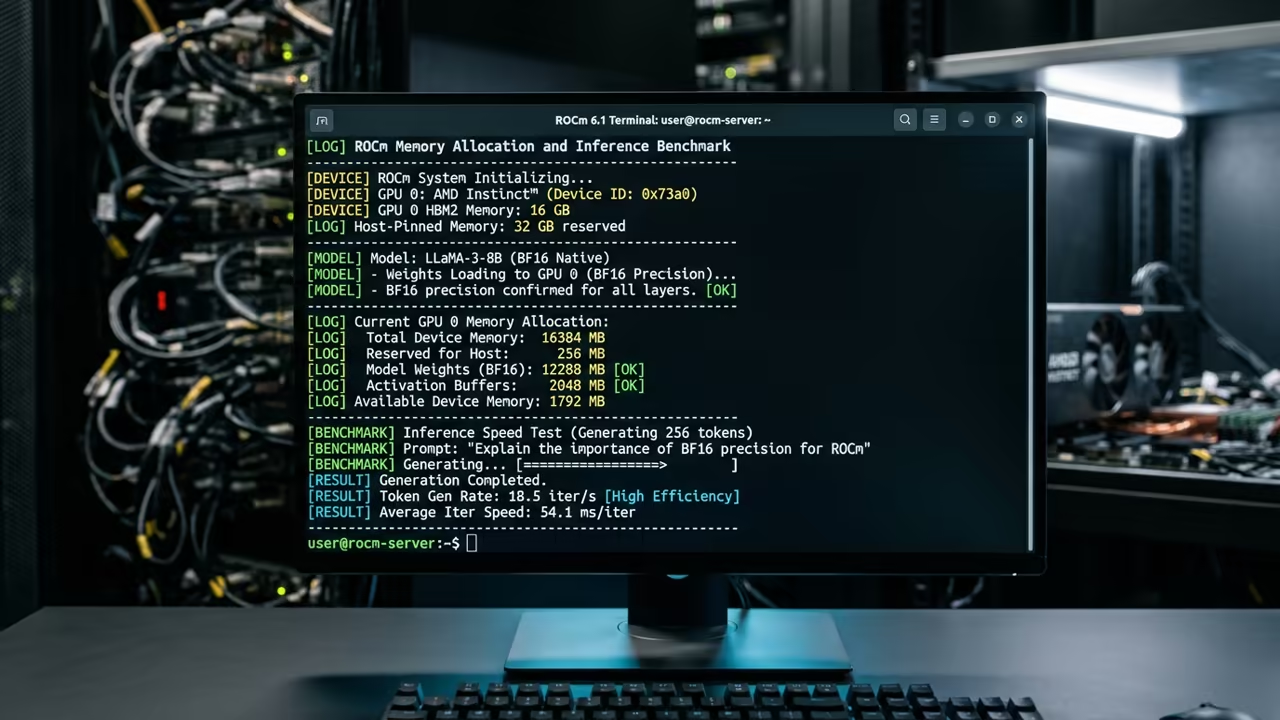
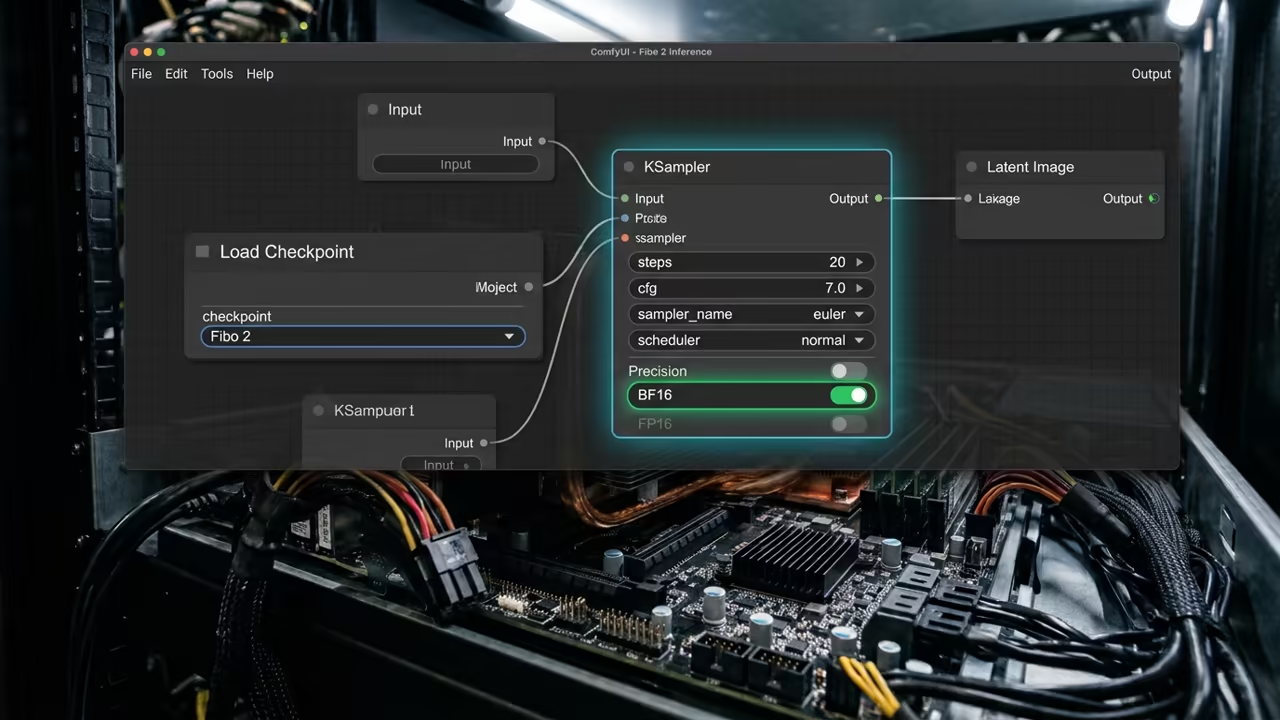
The AMD Instinct Mi60 uses the CDNA1 architecture which has native BFloat16 hardware units. Fibo 2 runs via PyTorch and ROCm which maps operations directly to these units.
This allows the entire model graph to stay in BF16 from the encoder to the VAE. There is no need to shift data between different precision formats during execution.
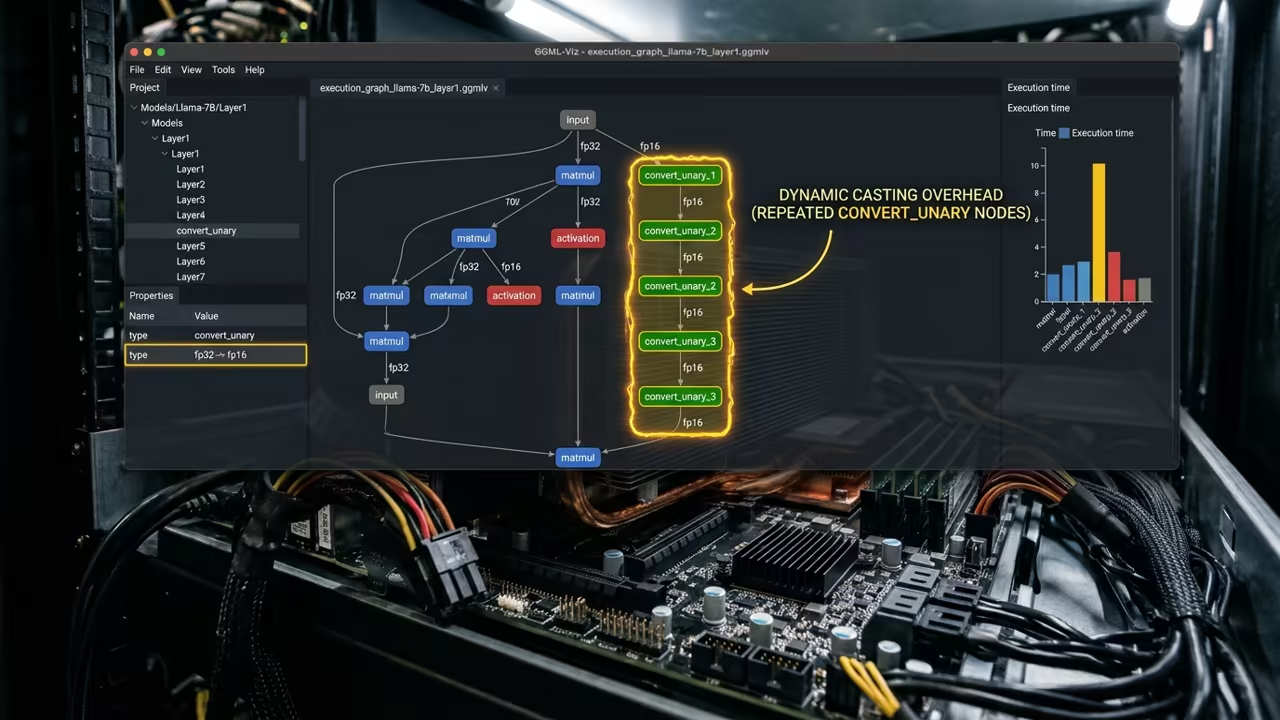
In contrast the lightweight C++ implementation relies on the GGML library for its execution pipeline. GGML often lacks native BF16 kernel coverage for every single operation on AMD hardware.
When GGML hits an operation that lacks a BF16 kernel it must cast the tensor. It uses convert unary nodes to shift the data into FP32 for processing.
This dynamic casting creates a massive overhead that consumes 8 to 15 percent of total time. Each cast triggers a separate kernel launch that adds significant latency to the GPU.
The GPU must constantly loop over tensors to shift and pad bits between layers. This process wastes precious memory bandwidth by pushing intermediate tensors through VRAM repeatedly.
You are essentially paying a performance tax every time a tensor changes its precision format. Native frameworks like PyTorch avoid this by using specialized ROCm kernels.
| Parameter | Description | Value |
|---|---|---|
| VRAM Capacity | High Bandwidth Memory | 32GB HBM2 |
| BF16 Support | Hardware Level Native | Supported |
| Interconnect | High Speed Fabric | Infinity Fabric |
| TDP Efficiency | Enterprise Grade | Optimized |
| Parameter | Description | Value |
Optimizing Your Local Stack
One insider detail for Mi60 owners is to prioritize ComfyUI over GGML based tools. Using the ROCm backend allows Fibo 2 to utilize the hardware units without casting.
Ensure your ROCm version matches the specific kernel requirements of the Fibo 2 model. This removes the convert unary bottlenecks and restores your lost inference speed.
This architectural breakthrough connects directly to our previous deep dives into VRAM orchestration. Mastering the precision flow is the only way to maximize enterprise hardware.
Learning and Support
Reach out for personalized technical help to optimize your AI stack today. Dive deeper into the same secrets with our online tutorials.
Online Tutorials and Technical Help
🚀 Recommended Resources
Disclosure: Some of the links above are referral links. I may earn a commission if you make a purchase at no extra cost to you.
Leave a Reply